
Write per-sample kernels in Python, with derivatives. Part of the RAPTOR family.
Write a numerical kernel for one sample as a plain Python function. hawk compiles it for the GPU or the CPU and derives its gradient (reverse mode) and tangent (forward mode).





hawk is the kernel-authoring layer of the RAPTOR family: write a kernel once at the level of your application, and hawk derives its forward- and reverse-mode derivatives and compiles it for host or device through eagle. See where RAPTOR fits for the full four-part story.
Read the documentation — installation, a five-minute quickstart, tutorials, examples and the full Python API reference.
Runs on CPU.
import numpy as np
import hawk
from hawk import Param, Scalar


@hawk.kernel
def scale(x: Scalar, a: Param, b: Param) -> Scalar:
    return a * x + b


print(scale(np.arange(4.0), 2.0, 1.0))
# [1. 3. 5. 7.]
The function is the kernel for one sample; scale(x, 2.0, 1.0) runs it over the whole array and gives back what it
returns (a value, a tuple, a list or a dict of them). The first call builds it and caches the build; the same call runs on the GPU
when x is a CuPy array. Every form, executed
· what a call does.
Runs on CPU.
import pathlib, tempfile

import hawk
from hawk import Kernel, Mutable, Scalar, Vector
from hawk.diff import vjp
from hawk.math import dot

@hawk.kernel
def energy(v: Vector[3], out: Mutable[Scalar]):
    out = 0.5 * dot(v, v)

energy_vjp = Kernel("energy_vjp", vjp(energy, wrt=("v",)))
work = pathlib.Path(tempfile.mkdtemp())
bundle = hawk.build([energy, energy_vjp], work, targets=("host",))
import numpy as np
v = np.array([[1.0, 2.0, 3.0, 4.0], [0.0, 1.0, 0.0, 1.0], [0.0, 0.0, 1.0, 1.0]])
e = np.zeros(4)
hawk.run(hawk.load(work, "energy"), v=v, out=e)
print("energy:", e)
# energy: [0.5 2.5 5. 9. ]bar_out = np.ones(4) # seed: d(loss)/d(energy) = 1 for every sample
bar_v = np.zeros((3, 4))
hawk.run(hawk.load(work, "energy_vjp"), v=v, bar_out=bar_out, bar_v=bar_v)
print("gradient d(energy)/dv:")
print(bar_v)
# [[1. 2. 3. 4.]
# [0. 1. 0. 1.]
# [0. 0. 1. 1.]]energy = 0.5 |v|^2, so d(energy)/dv = v exactly — the printed gradient above is the input v. Output above
is the notebook's own: docs/content/tutorials/04_gradients_backward.ipynb. hawk.diff.jvp derives the forward-mode (tangent) twin the same way.
Five-minute quickstart · install: pip install raptor-hawk raptor-eagle matplotlib (CPU route, no extras), or pip install "raptor-hawk[cuda12]" "raptor-eagle[cuda12]" for the GPU route
A kernel is a plain Python function decorated @hawk.kernel, one sample at a
time; its parameters are its declared planes (Scalar, Vector[3], Mutable,
...) and its body writes ordinary arithmetic:
import hawk
from hawk import Mutable, Scalar, Terminated, Vector
from hawk.math import maximum, norm

@hawk.kernel
def running_apogee(position: Vector[3], terminated: Terminated,
                    r_max: Mutable[Scalar]):
    r_max = maximum(r_max, norm(position))
Running statistics: read it before you write it
A Mutable parameter such as r_max is an ordinary local variable: read
it before you assign it and you get the value it held when THIS launch
began, which is how a running statistic is written — a launch reads what
an earlier launch left behind, and writes a new value on top of it. Your
buffer remembers; the kernel reads what it remembered. The host owns that
memory: it must initialise r_max before the first launch and preserve it
between launches — hawk never zeroes or scratch-allocates a plane a kernel
reads from. That memory is not differentiable: a launch-start read is a
recurrence across launches, and hawk keeps no tape across them, so
hawk.diff.vjp/jvp refuse a kernel that reads one — differentiate the
per-launch term on its own instead. A STEP kernel's whole rollout is the
exception a runtime handles: hawk.diff.tape(kernel, window) builds the
step's taping twin, which records the state every step read, so a
launching runtime can reverse the rollout window by window
(Tapes and events).
hawk is also a language you extend to your field: declare your own vocabulary once and every kernel speaks it. See hawk in your domain, with a worked orbits example.
Kernel kinds and returned outputs
A kernel may commit through several sinks — the places a kernel's
result goes: declared Mutable parameters (Output.named(...)),
a return <expr> committed into a synthesised slot (a result sink
hawk creates for you rather than one you declared as a parameter;
Output.returned(ttype, slot=...) names it), or both together — a
returned acceleration alongside an ordinary diagnostic Mutable the body
also writes:
from hawk import Param
from hawk.ext import Kind, Output

ACCEL = Kind("drag", output=Output.returned(Vector[3], slot="acc"))

@ACCEL
def drag(velocity: Vector[3], k: Param, speed: Mutable[Scalar]):
    speed = norm(velocity)          # an ordinary named sink
    return (-k * norm(velocity)) * velocity   # the returned slot, "acc"
Kind(...) also has a class-form spelling — sugar over the same object, one
kernel-authoring style closer to a plugin author's own vocabulary: an
annotated class attribute is a vocabulary entry, a plain-assigned one sets
one of Kind's own fields (output, sink, guard, ...), and anything
else refuses.
from hawk.ext import KernelKind, Output

class Accel(KernelKind, slug="drag"):
    output = Output.returned(Vector[3], slot="acc")

@Accel
def drag(velocity: Vector[3], k: Param):
    return (-k * norm(velocity)) * velocity
Read a table at a computed position, and keep its gradient cheap
hawk.math.index(x, n) turns a float into an index into n slots (truncated, held inside 0 .. n-1), and
theta[i] reads that slot. The gradient of such a read is one add into the slot that was read, so a wide
spline table differentiates without a column of selects per read. It works inside a for, also with a
dispatch in the body, which reverses as a rolled loop; a break in the middle of a loop differentiates
too. The index clamps, so a wrong position reads the end slot instead of failing.
@hawk.kernel
def curve(x: Scalar, theta: Vector[16], y: Mutable[Scalar]):
    u = x * 15.0
    f = hawk.math.floor(u)
    i = hawk.math.index(f, 15)          # a runtime index
    y = theta[i] * (1.0 - (u - f)) + theta[i + 1] * (u - f)
Worked, with the gradient checked against finite differences, in
Lookups, scatters and sums.
hawk.diff.param_planes(kernel, per_cell=True) lets one launch run many parameter values, each sample reading its own
entry (Gradients, backward).
A kernel can also draw its own random inputs inside the launch, the same on the CPU and the GPU
(the ensemble example).
Free-threaded CPython (3.13t/3.14t) is supported: the compiled modules declare GIL-free operation and the GIL stays disabled after import. Any number of threads may call module-level functions, build, compile, plan and cache concurrently. Distinct objects may be used from distinct threads without synchronisation. One stateful object (a stream, capture, launcher, graph, composer, plan, pipeline, active set, host kernel or arg block) shared by several threads is memory-safe — its calls serialise and a consumed object raises — but the ORDER of those calls is the caller's responsibility, exactly as for a NumPy array or a CuPy stream. CUDA adds two rules of its own: a stream capture is begun, filled and ended by one thread, and while any capture is open no thread may synchronise the whole device (stream-level synchronisation is fine). GPU routes are supported on free-threaded 3.14; on 3.13t the CPU route runs. hawk's compile cache is shared safely between threads, and a sealed-path kernel's cache key follows the user headers it includes.
pip install raptor-hawk raptor-eagle matplotlib          # CPU: no GPU, driver or CUDA packages (matplotlib is for the tutorials' plots)
pip install "raptor-hawk[cuda12]" "raptor-eagle[cuda12]"    # GPU: hawk compiles, eagle runs; [cuda13] on both for CUDA 13
Extras, platforms, requirements and the CPU-only route: installation.
Every number in this section is generated from the performance cards committed in eagle (benchmarks/perf_card and benchmarks/rk78_card):
tools/sync_perf_claims.py rewrites them, and tests/test_perf_claims.py fails if this text, the snapshot docs/perf_claims.json or (with RAPTOR_EAGLE_ROOT set to an eagle checkout) the cards disagree.
Kernels authored with hawk are what eagle's performance card times.
hawk + eagle (eagle.simulate) integrates 1,000,000 RK4 oscillators, each stopping at its own step, in 613 µs on an NVIDIA H100 80GB HBM3 (199 µs for 100,000), 2.5×–600× faster than NVIDIA Warp (2.5×), JAX (76×), CuPy (600×), PyTorch with torch.compile (130×) at N = 1,000,000 (1.1×–1700× at N = 100,000), in 40 MiB of GPU memory
— and, on the NVIDIA H100 80GB HBM3 reference GPU, the same hawk kernel, unmodified, integrates 1,000,000 adaptive
RK7(8) orbits in 43.6 ms; on a CPU alone, through eagle's host team, the same batch takes 3.76 s on 8 threads of an AMD EPYC 9B45 (the no-GPU route, for machines without a GPU). This is the regime hawk + eagle's
compaction targets (many samples stopping at different times); in other regimes the other tools hold their own. On a
dense workload where nothing finishes early, NVIDIA Warp is the fastest arm on that H100 at N = 1,000,000
(1.71 ms vs 1.75 ms for eagle.simulate, which takes 2.5% longer), while at N = 10,000 on the same workload
eagle.simulate is ahead (112 µs vs 121 µs). The development card the tutorials teach on is the Quadro P2000; its numbers are on the performance page next to every other device. See
eagle's performance page for every number, every arm,
including the ones where it doesn't win.
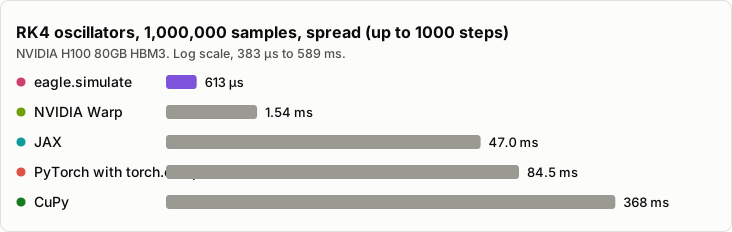
The chart shows one GPU; the performance page has a tab for every device and CPU measured.
The same hawk kernel also runs on a CPU alone, through eagle's host team: on an AMD EPYC 9B45 (8 cores, 16 logical CPUs) the 8-thread spread S=1000 batch of 1,000,000 samples takes 142 ms. eagle's performance page has a tab for every CPU and GPU measured, with Numba, JAX, PyTorch, NumPy and multiprocessing on the CPU cards, each with the setting where it fits best; on some cells and CPUs another tool is ahead, and the card shows which.
The pip-only device compile, directly
The device compile hawk.artifact.build/build_bundle use when no nvcc
is on $PATH goes through hawk.compile.device/hawk.compile.cubin; the
same entry points are usable directly, for an ad hoc CUDA C++ source
string that was never authored as a traced hawk kernel at all:
from hawk.compile import cubin, cubin_available

if cubin_available():
    image = cubin(source)          # DeviceImage(image=<SASS bytes>, target="cubin", arch="sm_XX")
cubin_available() never raises; device(source, target="ptx") is the
alternative when PTX (the portable intermediate form NVRTC can also emit)
is what a caller needs, guarded against a driver too old to JIT a newer
NVRTC's PTX (target="cubin" needs no such guard — it is already SASS,
the GPU's own machine code). Headers come from aether_dsc's sealed
payload — a copy of the headers hawk's device compiler reads from
directly, bundled into the wheel — never from disk.
Build and test from a source checkout (development)
Clone aether and eagle next to this checkout (so ../aether
and ../eagle sit beside hawk/), then install aether's sealed header
payload before hawk itself:
pip install ../aether/dsc
pip install -e .[test]
pytest -m "not gpu"
The compiled half (hawk._core) is a nanobind extension built through
scikit-build-core; pip install -e . builds it via CMakeLists.txt,
resolving the aether/eagle C++ header roots from those sibling checkouts
(or $HAWK_AETHER_INCLUDE/$HAWK_EAGLE_INCLUDE). -m "not gpu" deselects
the tests that need a CUDA GPU and cupy; most of the rest additionally
need eagle installed as a Python package to execute traced kernels on host
or device (see the "Python package" section of
eagle's README).
hawk write it (this repo) · eagle run it · aether the numerics core · raptor the shared contracts — the RAPTOR family
Apache-2.0 (see LICENSE and
NOTICE) · cite via "Cite this repository"
(CITATION.cff; every tagged release is archived on Zenodo: doi:10.5281/zenodo.23250242) · built to
make GPU computing accessible on modest hardware, for research and education. Collaboration is the point, and a
citation is the currency — get in touch.