




AI research fellow at the Air Force Research Laboratory. My background is business intelligence and data analytics at Forrester Research and New Balance; I now build data pipelines, LLM and agent evaluations, and GPU inference infrastructure.
BigQuery · dbt · MetricFlow · LangGraph · LangSmith · Ollama · GitHub Actions
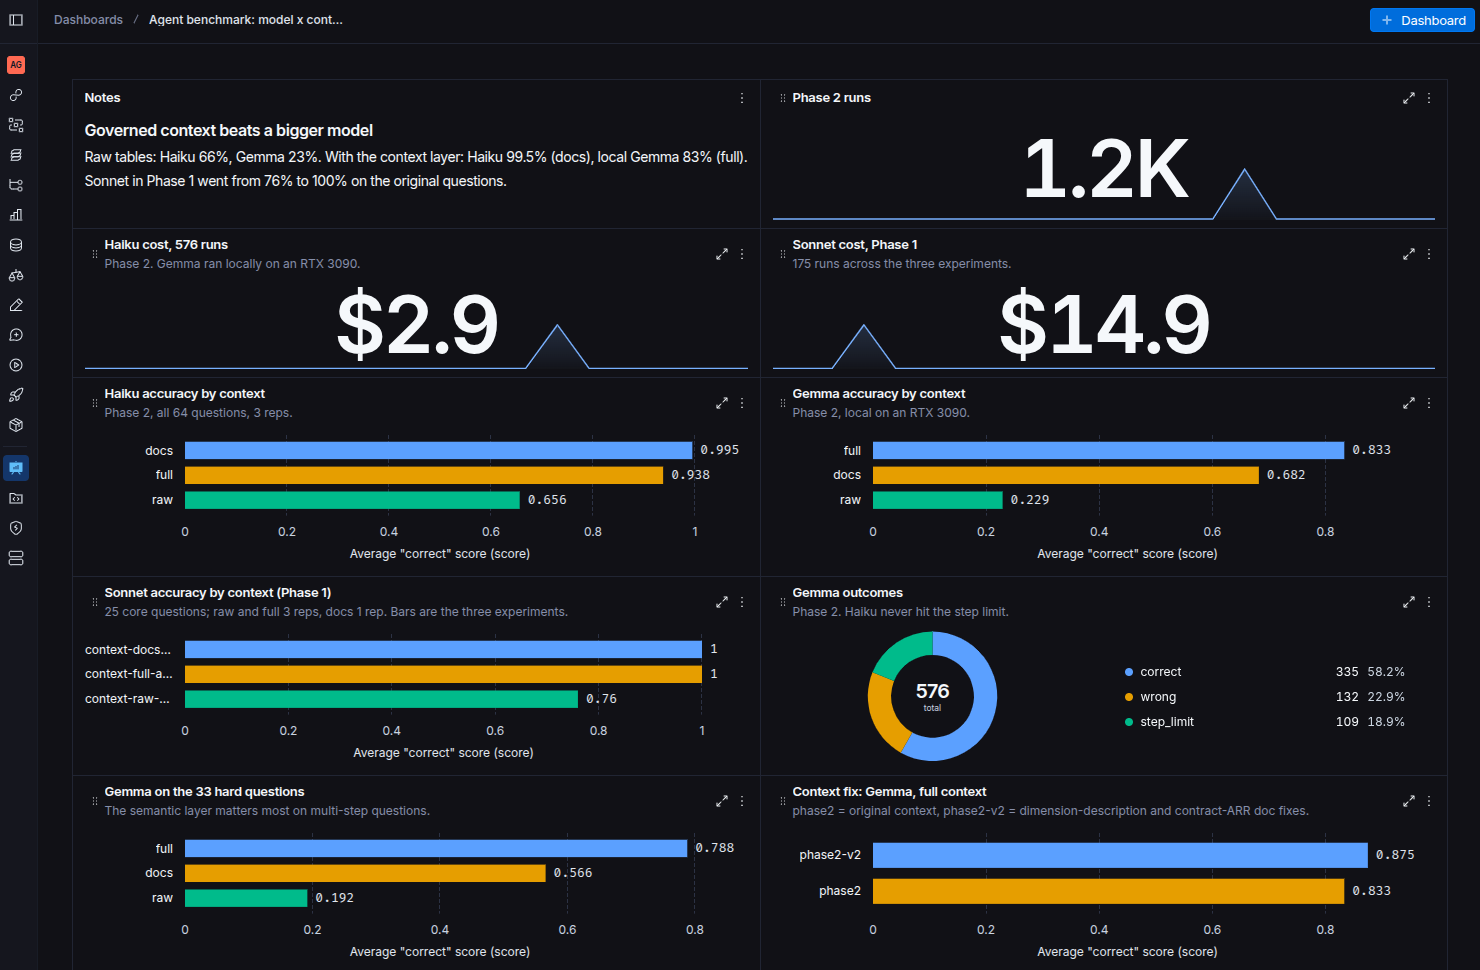
A benchmark that measures how much a governed context layer (dbt docs, a MetricFlow semantic layer, and written business guides) changes a data agent's accuracy, cost, and latency, and whether it lets a small local model compete with an API model. The data comes from a seeded simulation of a fictional developer-tools SaaS company with 13 planted data traps, and every answer is scored in code against an answer key.
- Ran 1,152 agent executions (64 questions, 3 context levels, 2 models, 3 runs each) and reports question-clustered bootstrap intervals.
- The context layer took local Gemma 4 26B from 23% to 83% accuracy on one RTX 3090 and cut its gap to Claude Haiku 5.5 from 43 points to 10, though not to parity.
- Traced every remaining full-context error to a cause, including a semantic-layer dimension that reports current state. Fixing its description took those questions from 2 of 12 runs correct to 11 of 12.
- Full context used 63% fewer input tokens and 59% less time than raw tables. CI reruns the context eval on every pull request that changes the context layer and posts the result as a comment.
dbt · Snowflake · DuckDB · Streamlit in Snowflake · Hightouch · Salesforce · LookML
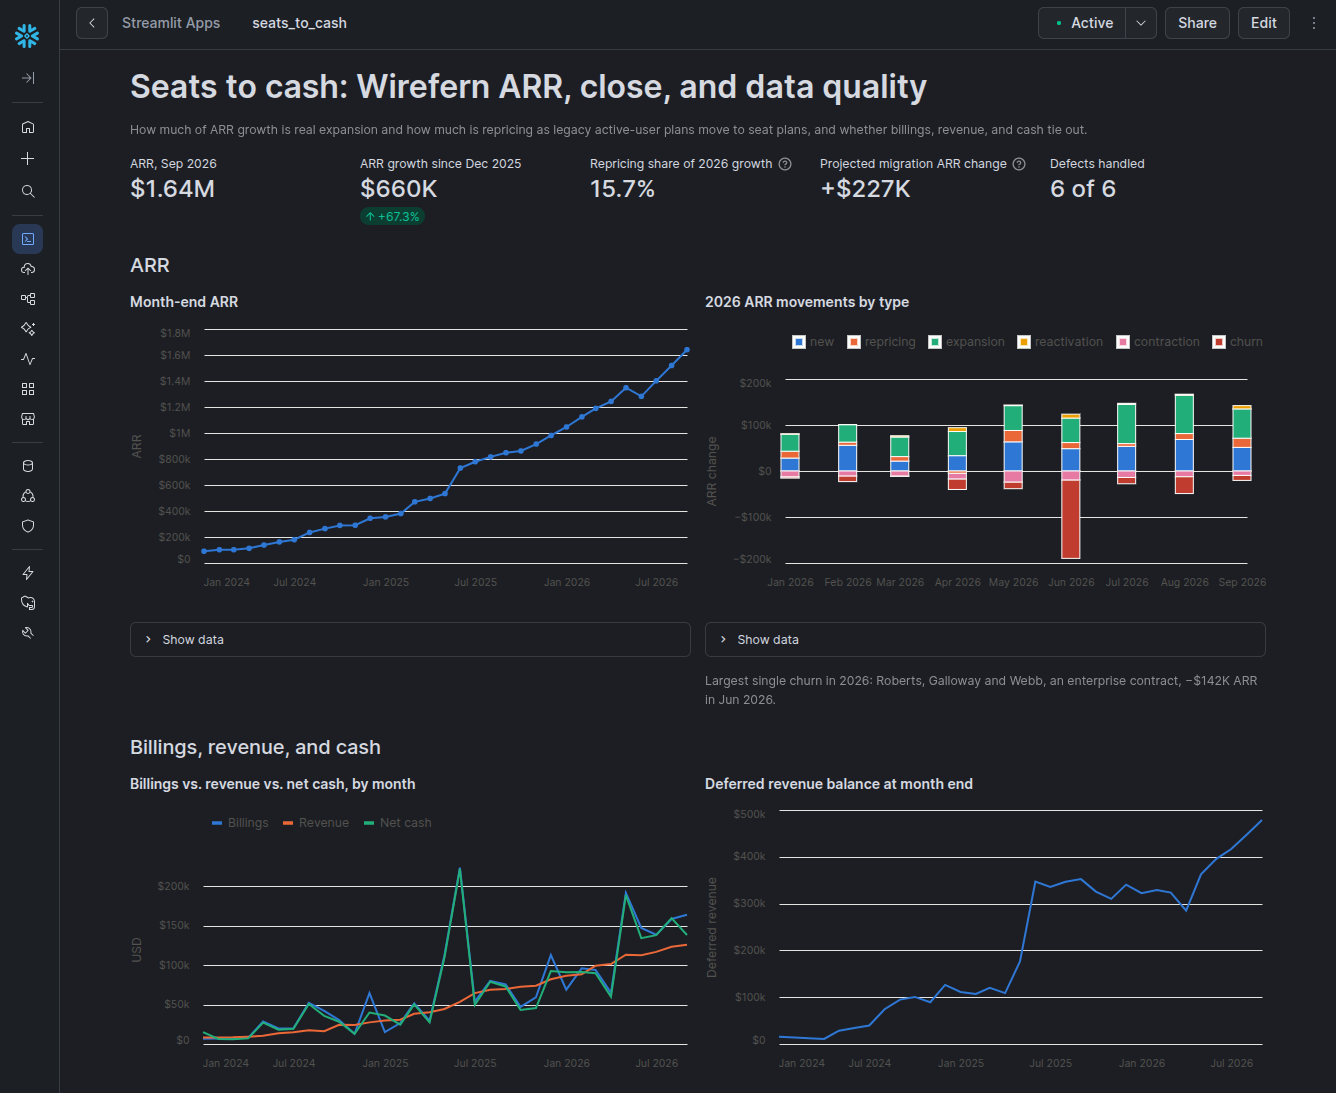
A finance data stack for a fictional product-led SaaS company, where every number is checked against an answer key. It answers a real finance question: how much of ARR growth is real expansion, and how much is repricing as legacy plans move to per-seat pricing, and do billings, revenue, and cash tie out along the way?
- Separates repricing from expansion in the ARR waterfall: $103K of 67% ARR growth was repricing, with a further ~$227K of exposure still ahead across 453 legacy accounts.
- Reconciles billings, revenue, deferred revenue, and cash to the cent, and matches 14,924 of 14,924 customer-months of MRR against the answer key, with six planted data defects all handled.
- Runs immutable month-end closes on an append-only ledger, tracing every restatement to the late-arriving rows that caused it.
- Runs the same dbt project (129 nodes, all tests passing) on DuckDB and Snowflake, reports through Streamlit in Snowflake, and reverse-ETLs account signals to Salesforce via Hightouch.
Databricks Asset Bundles · Lakeflow Declarative Pipelines · dbt · PySpark · MLflow · AI/BI Dashboards
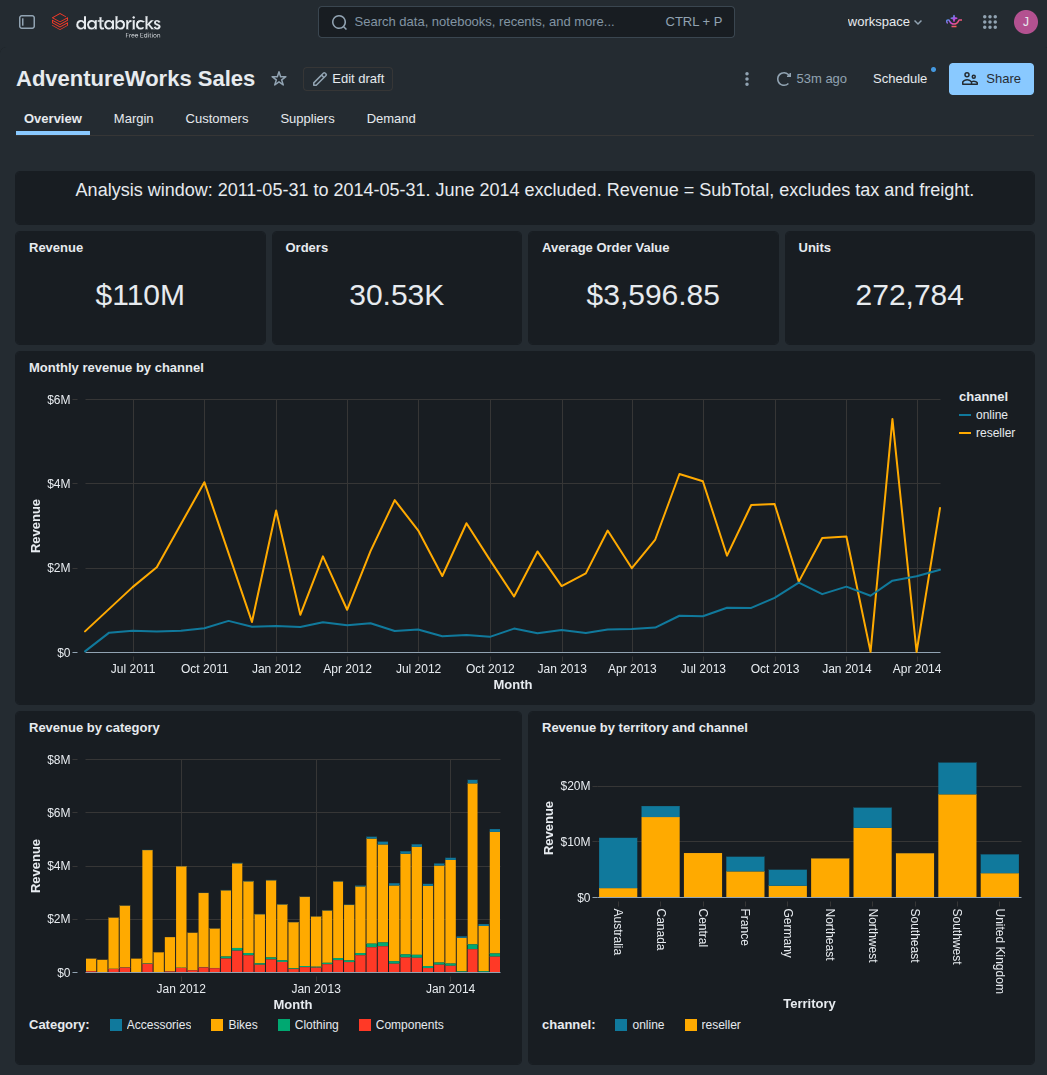
A medallion lakehouse on Databricks that turns a broken 72-file CSV export into a tested dbt star schema, MLflow-tracked analyses, and a five-page AI/BI dashboard, all deployed as one Asset Bundle.
- Bronze: repairs headerless, mis-encoded, and malformed files with config-driven fixes, verifying every load against expected row counts.
- Silver: 20 typed tables in a Lakeflow pipeline with data-quality expectations on keys, foreign keys, and required columns.
- Gold: 34 dbt models and 148 tests, including revenue reconciliation and effective-dated cost history for margin analysis.
- Analysis: customer segmentation, forecasting backtests, margin, and supplier quality, tracked in MLflow. Findings include a 40% online vs. 0.6% reseller margin split and an honest result that forecasting does not beat a naive baseline at this grain.
Azure Database for PostgreSQL · Azure Managed Grafana · Python · SQL · River
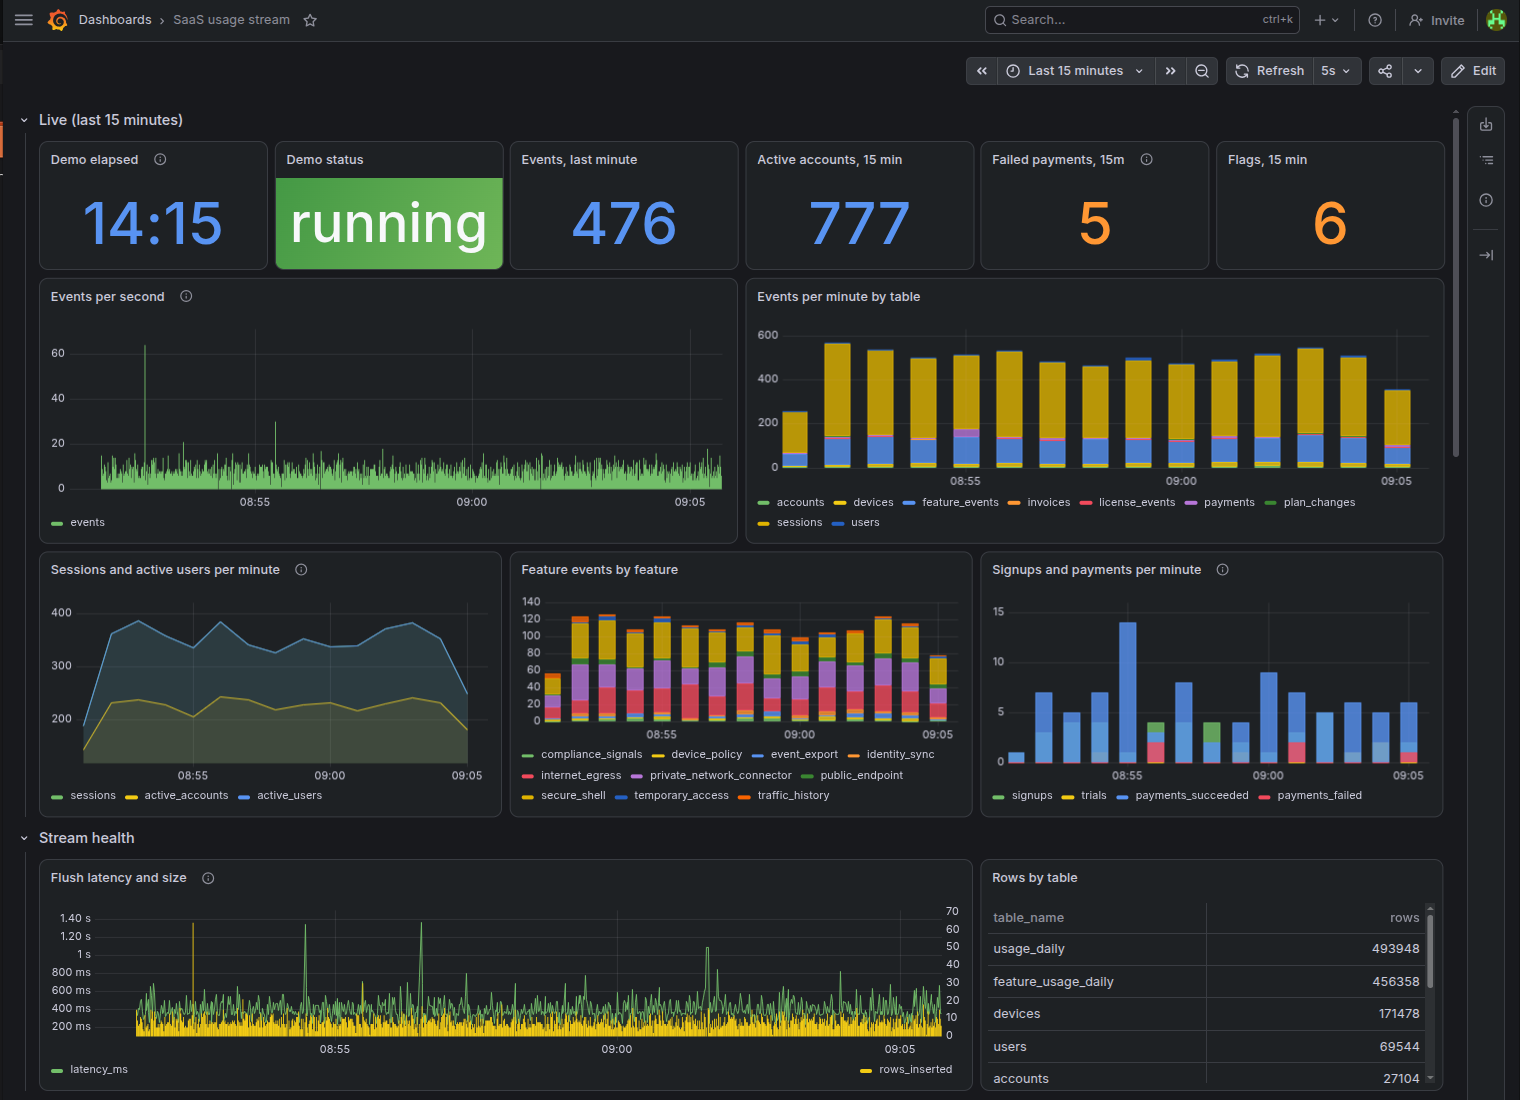
A real-time analytics pipeline for a simulated B2B SaaS company. CRM, product, and payment data stream into Azure PostgreSQL at about 500 events per minute, feeding a live Grafana dashboard, an outlier detector, and an online model that predicts which free trials convert to paid.
- Loads 1.25 million rows of history, then streams live events in one-second transactions. Consumers read past their own watermarks and write idempotently, so a take can be reset and replayed exactly in about 3 seconds.
- Flags anomalies about 2.5 seconds after they land, with perfect recall and precision on duplicate payments and negative invoices across 517 labeled injections.
- Caught a label leak in its own evaluation: an apparent 0.71 AUC came from when trials were scored. Fixed day-7 scoring gives an honest 0.54 from a calibrated model whose main signal is prior personal use (52% vs. 30% conversion).
- Serves a 42-panel Grafana dashboard through a read-only role that can see only dashboard views.
- U.S. Retail Sales Time Series in SQL — Analyzed 29 years of U.S. Census retail data in PostgreSQL using window functions, regression aggregates, change-point detection, and three-year forecasts with prediction intervals and backtests.
-
Next-Day Stockout Alerts — Built a LightGBM model on a layered SQL feature pipeline that ranks 50,000 perishable store-product series by next-day stockout risk, raising alert precision from 54.9% to 65.1% at 5,000 alerts a day, validated with a leakage test, rolling-origin backtest, and store-clustered bootstrap intervals.
-
Freight Broker Boom and Bust — Analyzed 99,281 real FMCSA broker authority records with a from-scratch Kaplan-Meier estimator, log-rank tests, and restricted mean survival time, showing that brokers who entered during the 2021-2022 freight boom lost their authority faster than earlier entrants.
-
Freight Cost & Sampling Analysis — Analyzed a 500,000-trip synthetic freight network using sampling simulation, cost-driver analysis, confounding controls, and route segmentation to produce operational decision insights.
-
Gemma 4 Security-Advisory Evaluation — Designed and analyzed a 3,900-run controlled experiment measuring how model size, supplied evidence, reasoning configuration, and temperature affect accuracy, latency, reliability, and deployment trade-offs.
-
Synthetic UAV Telemetry Evaluation — Compared seven synthetic time-series generation approaches across two UAV datasets using statistical diagnostics and train-synthetic/test-real predictive evaluation.
-
Grateful Dead Lyric Analysis — Tested whether the Grateful Dead's 50 most-played songs are lyrically simpler across 309 transcriptions, showing that type-token ratio is biased by song length and using MATTR, weighted log-odds, and NMF topic models to find that the real difference is subject matter.
-
SCIO Ontology Validation — Combined literature analysis, LLM-assisted evidence coding, embeddings, clustering, network analysis, topology, and structured review to evaluate a socio-cognitive influence ontology.
-
News Acquisition Feasibility — Tested whether open tools can supply a reliable news corpus for persuasion analysis by collecting 246 articles from 30 U.S. outlets through Media Cloud and Trafilatura with a robots.txt-compliant crawler and two Gemini completeness judges, finding 62% to 72% complete-text yield overall and up to 89% from a curated outlet list.
-
DOME Handbook RAG — Built a local RAG application and evaluation suite containing 6,672 question-level results across retrieval strategies, embedding models, and language models.
-
CiteBench — Developed a reproducible benchmark comparing citation-extraction workflows across PDF, text, vision, targeted-context, hybrid, and specialist-parser approaches.
-
Agentic Development Workflow — Designed a vendor-neutral, human-governed methodology for planning and executing analytics and AI projects with coding agents, with structured scoping, role separation, and quality gates.
Analytics engineering and data modeling · Business intelligence and decision support · Financial and revenue analytics · Statistical analysis and experimental design · Predictive modeling and forecasting · NLP and RAG · AI agent evaluation and context engineering · Model evaluation · Synthetic data and time series · Document intelligence · AI infrastructure
- Programming and Analytics: Python, SQL, R, JupyterLab, Excel
- Data Engineering and Modeling: dbt, MetricFlow, Snowflake, BigQuery, Databricks (Asset Bundles, Lakeflow), Apache Spark / PySpark, Delta Lake, DuckDB, Hightouch
- BI and Enterprise Platforms: Power BI, Tableau, Looker / LookML, Streamlit, Databricks AI/BI, Spotfire, SAP, Microsoft Dynamics 365, Salesforce, o9 Solutions
- Machine Learning and Applied AI: scikit-learn, LightGBM, SHAP, River, PyTorch, Hugging Face Transformers, LangChain, LangGraph, LangSmith, Pydantic, Ollama, vLLM
- Data and Retrieval: PostgreSQL, ChromaDB, Qdrant, Trafilatura
- Cloud, MLOps, and Infrastructure: Azure (Database for PostgreSQL, Managed Grafana), GCP, Vertex AI, MLflow, Docker, GitHub Actions, Linux, CUDA, Prometheus, Grafana