
Declarative SQL streaming pipelines for ClickHouse, with replay-aware builds and staged deployments.


SQLTide lets data teams define continuously updating ClickHouse pipelines in typed SQL, inspect the affected graph before making changes, and rebuild it from retained streaming history when logic changes.
It brings dbt-style authoring and deployment workflows to streaming workloads:
- Declarative models compile into ClickHouse tables and materialized views.
- Replay-aware builds reconstruct affected models from retained stream history.
- Safe planning shows the graph and warehouse operations before execution.
- Staged deployments support review, audit, promotion, and graph-level rollback.
- Built-in observability covers sources, lag, lineage, runs, quality checks, and sensors.
SQLTide currently targets ClickHouse and supports managed Kafka landing or adopted external stream tables.
Requires Python 3.12 or newer.
pip install sqltide
sqt --helpSQLTide is the new name for StreamBuild. Install sqltide in place of streambuild; the CLI is now
sqt. Names you author or configure change without a compatibility layer:
- Rename
streambuild_project.tomlandstreambuild_local.tomltosqltide_project.tomlandsqltide_local.toml, andSTREAMBUILD_*environment variables toSQLTIDE_*. - Import
sqltideinstead ofstreambuildin macros, sensors, and providers. - Trusted proxies send
X-SQLTide-Userby default, and browser sessions sign in again. - Ignore
.sqltide/instead of.streambuild/in your project's.gitignore.
State that SQLTide stores carries over automatically. The first sqt command against a target renames
its _streambuild_* metadata tables to _sqltide_*, and refuses while a StreamBuild run still holds
the target lock. Accounts in .streambuild/ or a shared control-store database are renamed the same
way. Managed Kafka sources keep their existing consumer groups, so ingestion resumes from committed
offsets. Upgrade every machine and CI job that writes to a target together: StreamBuild cannot read a
renamed target.
The included deterministic commerce demo runs locally with Redpanda and ClickHouse. It requires
Docker with Compose, Node.js 20.19 or newer, npm, and uv:
git clone https://github.com/sqlstack-io/sqltide.git
cd sqltide
make ui-install ui-build
uv tool install --editable .

cd examples/orders_demo
cp .env.example .env
make start
make dev
Open http://127.0.0.1:8000 to inspect three Kafka partitions, retained messages, replay-safe model
facts, tests, audits, and Kafka lag. See the commerce events demo
for its fixed event contract and controlled warning/recovery walkthrough.
Kafka or an adopted stream table
              |
              v
      retained landing data
              |
              v
 typed SQL models -> ClickHouse tables and materialized views
              |
              v
 plan -> build or stage -> audit -> promote
SQLTide follows __source() and __ref() dependencies to compile the model graph. Live
materialized views keep it current; retained replay columns let a later build reconstruct the
affected scope after SQL changes.
SQLTide uses SQLClean in process for SQL Rules and layout formatting. Default SQL Rules run during compilation, including compile, plan, build, and development-server compilation. Findings stop compilation before new artifacts are written; these commands never rewrite source. Models, SQL tests, and audits are checked in the adapter's dialect, using the same effective target, variables, declarations, and macro results as compilation. Diagnostics point back to authored SQL, including macro call sites.
sqt lint --project-dir .
sqt lint --project-dir . --json
sqt format --project-dir . --check
sqt format --project-dir . --diff
sqt format --project-dir .
sqt format --project-dir . --fix
lint is read-only and needs no warehouse connection. Both commands accept project-relative SQL
paths or directories and --target / --vars. format --check exits nonzero when layout changes
are needed; --diff previews without writing. Plain format changes layout only, preserving
headers, strings, comments, and opaque template calls. SQLClean's token-preservation and
idempotence checks remain enabled.
format --fix also attempts conservative model-only Rule fixes. The eligible codes are
SQLCLEAN002, 003, 005, 006, 008, 017, 025, and 042; SQLCLEAN003 requires the Snowflake dialect,
so it is not applied to ClickHouse. SQLClean042 additionally requires row-neutrality proof.
Each candidate must recompile with identical output columns/types/nullability, dependencies,
storage/aggregation semantics, replay lineage, and other models' SQL and diagnostics. Generated
macro text, tests, and audits are not auto-fixed. Unsafe or unproven fixes are left for the author;
remaining findings produce a nonzero exit even if safe layout changes were written.
Configure Rules in sqltide_project.toml:
[rules]
# Omit select for SQLClean's defaults; [] disables configurable Rules.
# Explicit SQLCLEAN selects the whole family, including opt-in Rules.
ignore = ["SQLCLEAN004"]

[rules.thresholds]
max_literal_length = 120
max_ranking_order_by = 2

[[rules.rule_exceptions]]
rule = "SQLCLEAN038"
path = "pipelines/pl__orders/order_summary.sql"
reason = "Reviewed cross join to one aggregate row"
relation = "order_totals"
select and ignore accept exact published SQLCLEAN codes or SQLCLEAN; lint and format
also accept --select. Reviewed exceptions require an exact code, an existing project-relative
file (not a glob), and a nonempty reason. Only SQLCLEAN038 supports relation and optional cte
scoping; these names match ASCII case-insensitively. When an evaluated Rule's exception no longer
suppresses a finding, remove or update that stale exception. Duplicate or overlapping exact
exceptions are rejected.
For deliberate broader path policy, use a separate reasoned ignore (not a glob exception):
[[rules.rule_ignores]]
rules = ["SQLCLEAN004"]
paths = ["pipelines/pl__previews/**"]
reason = "Preview queries intentionally use bounded unordered samples"
Path scopes use repository-relative POSIX globs; unlike exact exceptions, these ignores may
match no current finding. Alternatively, use selectors = ["model:order_summary"] or
selectors = ["pipeline:pl__orders"]. Selectors resolve only explicitly named resources:
model: covers only that model; pipeline: covers all its own models, not dependent
pipelines. Execution's downstream closure does not broaden ignore scope. Existing bare-name
and whitespace-union selector syntax also works; unknown, empty or deleted scopes fail validation. Paths and
selectors in one entry form a union. Layout formatting validates selector ownership through
connection-free compilation before writing; ignores also exclude semantic fixes.
Inline sqt: ignore / sqb: ignore comments are rejected, not treated as suppressions.
Intentional opt-outs are sql_analysis false in a MODEL, TEST, or AUDIT header,
[settings] sql_analysis = false in project configuration, or --no-sql-analysis for one
command. They skip configurable SQL Rules, not mandatory type inference, dependency,
replay, or realization validation. Layout-only formatting remains available for opted-out SQL.
sqltide_project.toml
sources/
  orders.yml
macros/
  common.py
pipelines/
  pl__orders/
    pipeline.toml
    order_totals.sql
audits/
tests/
Minimal configuration:
name = "orders"
default_target = "dev"

[connection]
host = "localhost"
port = 8123
username = "default"
password = "${ENV:CLICKHOUSE_PASSWORD}"

[defaults]
pipeline_mode = "direct"

[defaults.sources.kafka.retention]
duration = "7d"
timestamp = "broker"
fallback = "landed"
cap_at = "landed"

[defaults.models.retention]
duration = "7d"
timestamp_column = "kafka_timestamp"
cap_at_column = "ingested_at"
when_missing = "error"

[ui]
timezone = "Europe/London"

[dependencies]
model_reference_scope = "pipeline"

[[dependencies.allowed_cross_pipeline_references]]
upstream_pipeline = "pl__shared_dimensions"
downstream_pipeline = "pl__orders"

[targets.dev]
database = "analytics"
Developer-specific target and connection overrides belong in the gitignored
sqltide_local.toml.
Managed Kafka source:
sources:
  - name: orders
    kind: kafka
    broker_list: kafka:9092
    topic: source.orders
    replay_boundary:
      mode: offsets
SQLTide owns managed Kafka landing objects. It validates but never mutates adopted source tables. See the pipeline documentation for adopted stream-table configuration.
Typed retention defaults are checked against each compiled schema. A pipeline can override the
model default in pipeline.toml with [defaults.models.retention]; an individual table model can
override it with retention (...) or opt out with retention false. Specific models and sources
can continue to use free-form ttl expressions when adapter-specific behavior is required.
Each direct child of pipelines/ is a pipeline. Its directory name is its logical name:
pipelines/
  pl__orders/
    staging/
      orders_clean.sql
    order_totals.sql
Nested directories organize models but do not change pipeline identity. Pipeline, source, and model names share one namespace and must be unique.
Projects default to dependencies.model_reference_scope = "project", which permits model
references across pipeline directories for compatibility. Set the committed policy to "pipeline"
to keep model dependencies within their owning pipeline. Managed and adopted sources remain
shareable across pipelines under either policy.
Pipeline scope can grant narrow directional exceptions with
dependencies.allowed_cross_pipeline_references. Each entry permits models in
downstream_pipeline to reference models in upstream_pipeline; reverse access requires a
separate entry. Both pipelines must exist. These exceptions do not permit references between
direct and virtual pipelines.
MODEL (
  engine "MergeTree()",
  order_by ["order_id", "_replay_partition", "_replay_offset"],
);

SELECT
  order_id::String AS order_id,
  _replay_partition::Int32 AS _replay_partition,
  _replay_offset::Int64 AS _replay_offset,
  _replay_timestamp::DateTime64(3) AS _replay_timestamp
FROM __source("orders")
Models must project explicit output types. Table models preserve replay lineage through normalized
_replay_* columns. Terminal query views use MODEL (kind view).
Python functions under macros/ are available in model, test, and audit SQL as @function_name().
CONSTANT (name ..., value ...) declarations under constants/ and ENUM (name ..., members ...)
declarations under enums/ are validated once per compile and render as ClickHouse literals through
@const("name") and @enum("name").MEMBER, for example status IN @const("open_statuses").
sqt discover                 # inspect authored resources
sqt compile                  # offline validation and artifacts
sqt plan                     # read-only warehouse plan
sqt build                    # confirm and execute
sqt test
sqt audit
sqt dev                      # local UI at 127.0.0.1:8000
Select a model or pipeline with repeatable selectors:
sqt plan --select pipeline:pl__orders
sqt build --select order_totals --start-time 2026-08-01T00:00:00Z
sqt compile is offline. sqt plan reads warehouse state but cannot mutate it. sqt build replans
immediately before execution so an approved command never relies on a stale plan.
| Mode | Behavior | Best for |
|---|---|---|
| Direct | Rebuilds selected live relations immediately | Development and explicitly controlled live changes |
| Virtual | Builds deployment-specific relations before promotion | Review, validation, and production releases |
| Mixed | Stages virtual pipelines before applying direct pipelines | Projects containing both deployment strategies |
Set pipeline_mode = "virtual" project-wide or mode = "virtual" in pipeline.toml.
sqt build
sqt deployment list
sqt deployment show <deployment-id>
sqt deployment diff <deployment-id>
sqt deployment audit <deployment-id>
sqt deployment promote <deployment-id>
sqt deployment rollback --previous
Promotion and rollback switch stable views one relation at a time. Rollback restores a retained publication's bindings, not a historical data snapshot.
SQLTide can destroy selected deployed pipelines while retaining their authored definitions,
managed sources, and replay data. A target reset additionally removes managed source and replay
relations, but preserves every _sqltide_* metadata table, account and authorization state,
Kafka offsets, and the reset's own run evidence.
sqt destroy --target uat --select pipeline:pl__orders pipeline:pl__reporting
sqt reset-target --target uat
Both commands require an interactive terminal. They print a frozen impact plan, require a separate review decision, and then prompt for exact pipeline-name challenges from that plan. There is no non-interactive approval option or administrator bypass. Execution locks the target, replans, and rejects manifest or warehouse drift before the first drop. Unselected downstream pipelines block a plan rather than being silently included. Standalone CLI execution also requires the local OS user to be an active built-in administrator in the SQLTide control store.
UI plans and their review state are durable, actor-bound, and atomically single-use across server restarts and workers. Standalone CLI plans use the same durable control-store representation.
Classify production targets in committed project configuration so reset requires the additional
exact PRODUCTION challenge even when the target has a non-standard name:
[targets.live]
production = true

[targets.live.destruction]
max_table_size_to_drop = "100GiB"
max_table_size_to_drop is an optional committed, target-scoped ClickHouse safety ceiling for
each relation, not the aggregate plan size. It must be a finite positive byte-size string and cannot
be overridden from sqltide_local.toml. SQLTide applies it only to that target's reviewed
destruction DROP statements, freezes the override and server default into each plan,
and still relies on ClickHouse to enforce the ceiling when every DROP executes. Other SQLTide
queries continue to use the target connection and server defaults.
Ownership generations, external dependants in every ClickHouse database, and target/database drift are checked before execution. Historical deployment metadata alone never authorizes deletion of a live same-name relation. Target mutation locks remain fail-closed after a crashed owner; SQLTide does not use an age-based automatic takeover that could overlap a long-running ClickHouse query.
The Pipelines UI exposes the same planner and executor through multi-selection and the dedicated
pipeline.destroy and target.reset permissions. Every generated statement, actor, challenge,
result, and observed remaining object after a partial failure is retained in Runs. A failed residual
catalog read is recorded as unavailable rather than as an empty target. Failed destructive Runs can
create a fresh recovery plan from their recorded root selection; old SQL and historical derived
closure are never replayed.
sqt dev serves a warehouse-backed interface for one resolved project and target. It provides:
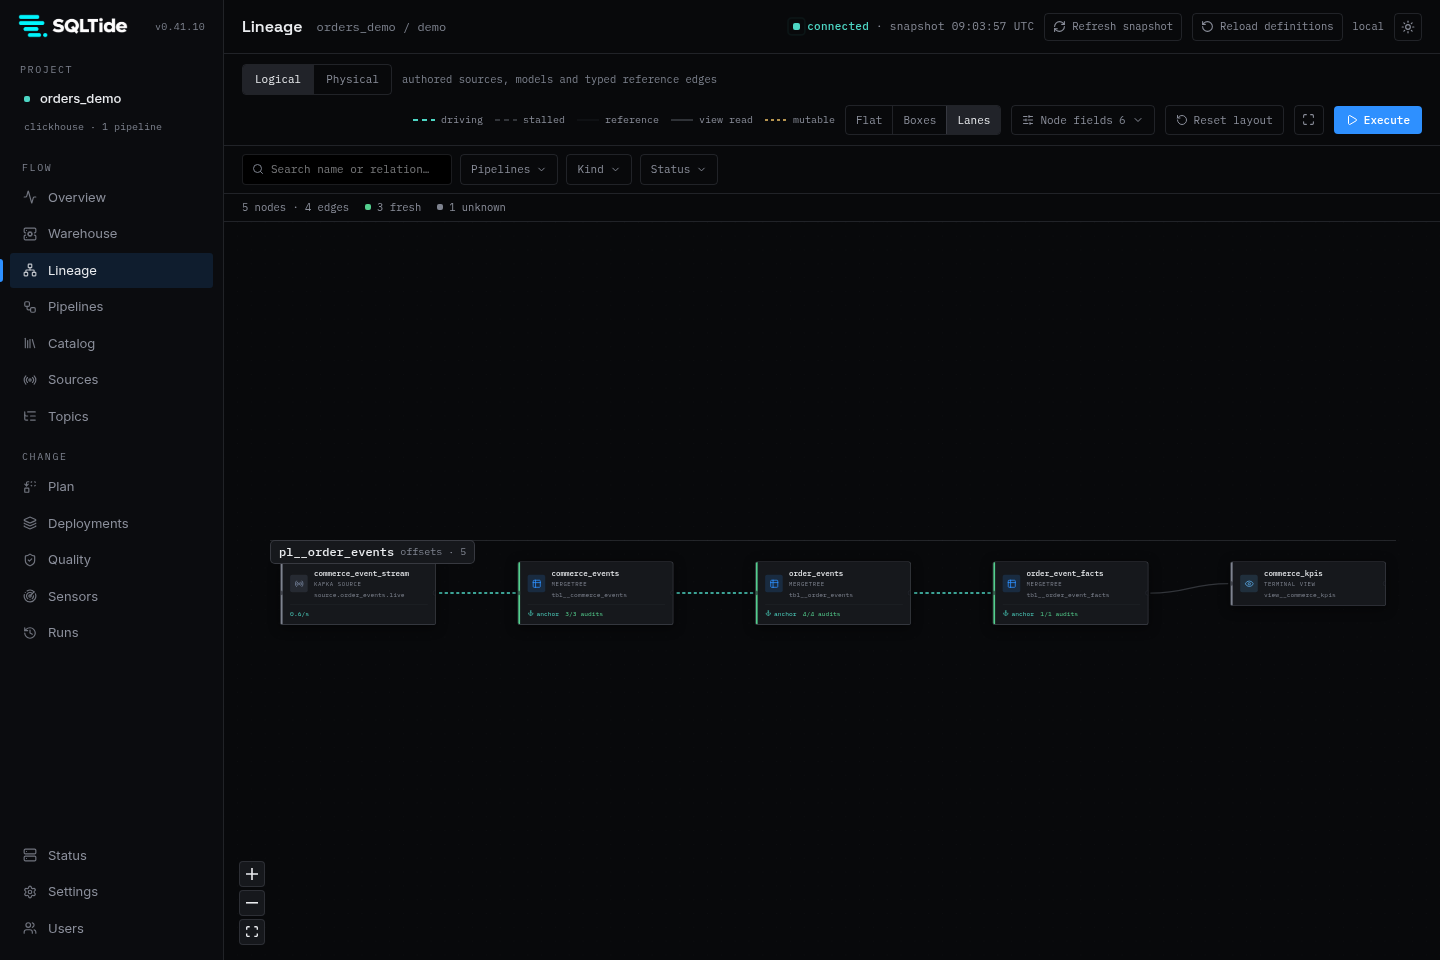
- overview, lineage, pipeline, catalog, source, topic, and message inspection
- connected plan previews and protected-pipeline confirmation
- direct, virtual, and mixed build execution
- deployment inventory, diff, promotion, and cleanup
- frozen bulk pipeline destruction and target reset plans with typed confirmation
- durable run timelines, statement progress, cancellation, and stale-run recovery guidance
- quality history, scheduler health, sensors, and dead-letter recovery
Run observability is warehouse-backed. A silent run becomes unresponsive after 45 seconds and
presumed_failed after [defaults].run_presumed_failed_after (default 10m). A new build is blocked
until that safety window expires to prevent overlapping warehouse writes.
Shared installations support trusted-proxy or password authentication with project-scoped roles. See the documentation for access control and operational configuration.
sqt compileis connection-free and writes disposable artifacts undertarget/.sqt planis read-only;sqt buildalways replans against current warehouse state.- Lifecycle state is append-only metadata in the selected target database.
- Failed or cancelled builds are rerun, never resumed from copied SQL artifacts.
- Workflow statements execute serially to avoid unbounded ClickHouse memory pressure.
Install the locked Python and UI dependencies before running the verification lanes:
uv sync --locked --all-groups
make ui-install ui-build
make check-ci
make ui-verify
make test
Run every verification lane with:
make test-allThe integration and browser lanes provision real ClickHouse and Redpanda containers, so Docker must be running. Install Chromium and its system dependencies before the first browser run:
uv run playwright install --with-deps chromium
make ui-install ui-build
make test-browser